
Your test suite reports 85 percent coverage and a bug still ships. Sound familiar? The number looks good, but coverage works across two dimensions at once, and most reporting only shows one of them. On mobile, where a layout shift or an OS update can quietly break a flow that passed yesterday, knowing which dimension you're actually measuring changes how you close the gaps. Minitap's autonomous QA agent reads your app from source, maps both dimensions automatically, and runs the full regression suite in about one hour, so coverage gaps surface before a release, not after one.
TLDR:
- Test coverage measures what risks got tested, beyond what code ran. A function can hit 100% code coverage and still return the wrong value.
- Calculate coverage with: (executed test units / total testable units) x 100. The denominator defines everything.
- Aim for 80% as a starting point, but payment, auth, and data loss paths warrant close to 100% on critical flows.
- Rank coverage improvement by risk, audit for duplicates before adding tests, and gate coverage in CI/CD so gaps surface at pull request, not release.
- Minitap is the answer: its autonomous QA agent reads your app from source, maps all test scenarios automatically, and runs the full regression suite on cloud iOS simulators and Android emulators in about one hour with zero maintenance overhead.
What Is Test Coverage in Software Testing
Test coverage measures how much of an application, its features, user flows, requirements, and code paths, has actually been exercised by your test suite. It answers a plain question: what did we test, and how much of it counts.
Coverage is a quality signal, not a guarantee. A suite can touch every screen in an app and still miss the one edge case that takes down checkout in production. Understanding software testing basics for mobile teams helps frame where coverage fits in the broader quality picture. Coverage works across two dimensions at once.
- Breadth: how many requirements, features, or user scenarios your tests actually reach
- Depth: how rigorously each scenario gets tested, meaning the range of inputs, states, and conditions checked, going beyond whether the happy path passes
Breadth tells you what's reached. Depth tells you whether each scenario was actually validated, not merely executed.
Test Coverage vs Code Coverage
Code coverage is a white-box measure. It counts lines, branches, and statements that executed while your suite ran, producing a clean percentage straight from the codebase. If you need a broader foundation, the QA mobile testing guide for engineering managers covers where code coverage fits within the full QA picture.
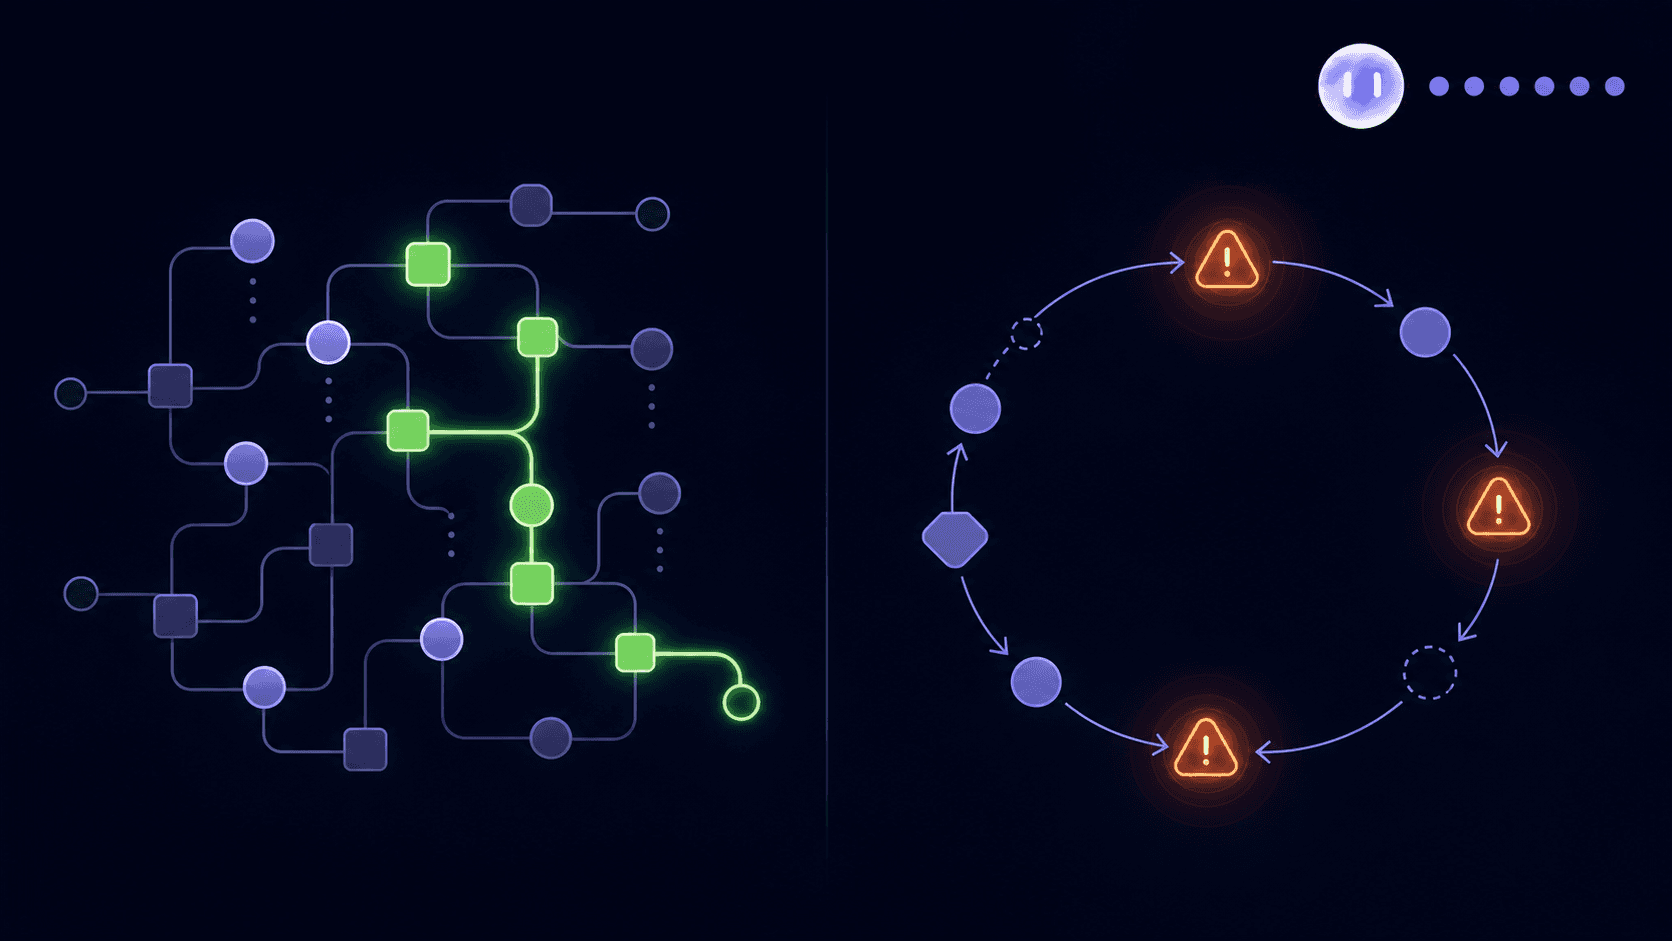
Test coverage asks a different question: whether requirements, user scenarios, edge cases, and risk areas are actually validated, regardless of which lines got hit.
The confusion causes real damage. Code that runs without being checked for correctness still counts toward code coverage. A function can hit 100 percent coverage and still return the wrong value every time.
| Code Coverage | Test Coverage |
|---|---|
| What code ran | What risks got tested |
| Lines, branches, statements | Requirements, scenarios, edge cases |
| Generated automatically from source | Requires mapping against user intent |
| Can hit 100% with weak assertions | Reflects actual risk reduction |
A team chasing a code coverage number can hit 90 percent and still ship a checkout bug, because the metric never checked whether that flow was tested from the user's point of view.
How to Calculate Test Coverage
Test Coverage (%) = (Number of executed test units / Total number of testable units) × 100
Execute 750 of 1,000 testable statements and coverage lands at 75 percent. The number only means something once you know what sits in the denominator, and that changes by what you're measuring:
- Statement or branch coverage: executed lines or branches over total lines or branches in the codebase.
- Requirements coverage: requirements with a passing test mapped to them over total documented requirements.
- Scenario coverage: flows exercised over total scenarios identified during test design.
A team can report 90 percent statement coverage and 40 percent requirements coverage on the same release. Both are correct, just answering different questions. The mobile app testing basics guide covers how these metrics fit into a complete testing strategy. Before quoting a percentage upward, ask what got counted in the denominator.
Types of Test Coverage Metrics
No single metric answers every question about your suite. Different metrics exist because different risks need different signals, and mixing them up creates false confidence.
Code-level metrics measure what executed, not whether it was validated:
- Statement coverage: percentage of executable lines run at least once, a floor check and not a quality signal.
- Branch coverage: percentage of decision paths (if/else, switch cases) exercised in both directions, catching the untested "else" statement coverage misses.
- Function coverage: percentage of functions or methods called at least once, useful for spotting dead code.
Product-level metrics measure whether the app works the way users and requirements expect:
- Requirements coverage: percentage of documented requirements with a mapped, passing test.
- User scenario coverage: real flows like login, checkout, or offline sync tested end to end.
- Risk-based coverage: high-risk areas (payments, auth, data loss) weighted by impact, not raw count.
- Compatibility coverage: OS versions and device sizes validated, especially critical given how fragmented mobile is.
95 percent statement coverage says nothing about your risk-based or compatibility numbers. Each metric answers its own question, not a stand-in for the others. Mobile automated testing is one of the primary levers teams use to move these numbers systematically.
What a Good Test Coverage Percentage Looks Like
80 percent shows up so often as a target that it's worth naming why: below that line, real risk tends to hide in the untested 20 percent, and above it, each additional point costs more than the last one bought you.
That target moves depending on what's being tested. Payment processing, authentication, and anything touching user data warrant close to 100 percent coverage on critical paths, because a gap there is not an edge case, it's an incident. A rarely used settings screen can sit well under 80 percent without costing you anything real.
Which 80 percent of your app gets covered matters more than whether the coverage number reads 80.
This is where coverage theater creeps in. A team under pressure to report a number can write shallow tests that touch a line without asserting anything meaningful, hit 85 percent, and still ship a broken checkout flow underneath that score. QA automation for mobile apps covers how to build assertions that actually reduce risk instead of inflating a percentage.
Why Test Coverage Matters for Mobile Apps
Mobile carries structural obstacles that web testing does not face. There's no DOM equivalent to anchor selectors against, so a layout shift, an OS update, or a new device variant can quietly break a test that passed yesterday. The same flow often gets written and maintained twice, once per OS, doubling the coverage work before a new feature ships. Regression testing for mobile apps explains why bugs slip through even when coverage numbers look solid.
Android fragmentation compounds this. A flow can pass on one device and fail on another because of a manufacturer skin or a different permission model. Coverage that looks solid on paper can hide gaps that only surface on specific hardware and OS combinations, turning into production escapes: a checkout flow untested on the device that fails, or a permission prompt no one caught. Brittle, selector-based tests accumulate this debt as AI coding tools speed up how fast new code ships, a pattern Forbes Technology Council has pointed to across teams. Script-based frameworks like Appium, Maestro, and XCUITest require selector maintenance every time the UI changes, and on mobile, where there is no DOM equivalent, that maintenance compounds faster than on the web. The mobile application testing framework a team chooses determines whether that selector debt accumulates on the engineering team or disappears from the equation entirely.
How to Measure Test Coverage in Practice
Six methods cover most of what teams actually need, each answering a different question about what got tested.
- Feature or requirements coverage: maps each documented requirement to a passing test. Fits best when a spec exists to trace against.
- Code instrumentation coverage: tools hook into the runtime and log which lines, branches, or functions executed. Fits unit and integration layers, not user-facing flows.
- GUI coverage: tracks which screens and UI states got touched during a run. Fits apps with heavy visual surface area.
- Risk coverage: weights tested areas by impact, so payment and auth get tracked separately from an unused settings toggle.
- User scenario coverage: measures whether real end-to-end journeys, login, checkout, offline sync, get exercised.
- State transition coverage: checks whether every valid state change has a test, catching bugs that only appear mid-transition.
A coverage matrix ties these together: rows list requirements or risk areas, columns list test cases, cells mark covered versus uncovered. Teams building these matrices often encounter flaky tests that distort which cells can be reliably marked covered.
How to Improve Test Coverage
Coverage improvement done backwards produces a number that climbs while risk stays exactly where it was. The order below reflects what actually moves the needle.
Audit before you add. Redundant tests inflate your denominator without reducing risk. Cut duplicates before adding new tests.
Write the strategy before the tests. Decide which flows matter, and why, before writing code.
Order by risk, not ease. Payment, auth, and data loss paths get covered first, even when harder to test than a settings toggle.
Put coverage reporting in CI/CD. A gap caught on a pull request costs a review comment. The same gap at release costs a hotfix.
Track coverage debt like technical debt. Log it, rank it, pay it down on a cadence instead of rediscovering it during an incident review.
Integrating Test Coverage into CI/CD
Coverage numbers tracked in a spreadsheet go stale the moment someone merges. Running coverage inside the pipeline turns it into something you act on before shipping.
Unit and integration tests run on every commit; targeted end to end tests on checkout, login, and payment run at every merge; full regression testing for mobile apps runs before the release cut.
Coverage gates enforce this automatically. A threshold tied to critical-path requirements, with a lower bar elsewhere, blocks the merges that actually carry risk, not the ones that clear an arbitrary percentage. CI/CD test automation best practices recommend quality gates that block deployment on failure, with no exceptions without a documented quarantine.
The Limits of Test Coverage as a Metric
A dashboard reading 80 percent answers one question and leaves the harder one untouched: did anyone check the output was right.
A test that runs a function and asserts nothing beyond "it didn't crash" still counts. So does an assertion loose enough to pass regardless of what the function returns. Coverage counts execution, not correctness, and a suite built to satisfy a gate can look thorough while catching almost nothing.
Mutation testing exposes this. It flips a conditional or changes a boundary value, then reruns the suite. Tests that still pass weren't checking that logic. Mutation testing measures assertion quality in a way coverage metrics cannot: a suite that catches every mutation has assertions that pull their weight. The complete regression testing guide covers how to pair mutation testing with coverage metrics to catch bugs before users do. High coverage paired with a low mutation score means the suite works in appearance only. The real check: would these tests catch a bug tomorrow.
How Minitap Approaches Test Coverage for Mobile and Web
The structural gaps above (no DOM equivalent, selector debt, edge cases too rare to script) are problems script-based tools cannot escape. Minitap answers them by reading the app from source code, mapping every integration and UI scenario automatically, and running the full regression suite on cloud iOS simulators and Android emulators in about one hour.
Because coverage comes from the codebase itself, it reaches low-frequency edge cases that never made a test plan, and it does not decay as the product changes. Minitap owns authorship, execution, maintenance, and root cause analysis, so the suite stays current without anyone rewriting a selector after a redesign.
Minitap benefits engineering teams that ship software and want to eliminate test maintenance and reduce engineering time spent on QA. It is especially valuable for high-cadence organizations, meaning teams that release weekly or faster, are slowed by manual regression work, maintain brittle selector-based tests, or use AI-assisted development tools that have accelerated implementation velocity. Minitap covers iOS, Android, and web from a single specification, ending parallel suite maintenance across platforms. For teams shipping both mobile and web, a single autonomous agent replaces separate toolchains entirely.
Every run ships a session trace, screenshots, and a written explanation of each finding. According to Minitap, over 100 million people use apps tested by miniTest.
Final Thoughts on Building Test Coverage That Holds Up
Coverage without depth is just a number that looks good until something breaks in production. The real question is whether the flows that matter most, meaning payment, authentication, and onboarding, were actually validated, not merely executed. Connect your codebase to Minitap and its autonomous agent maps every testable scenario from source, runs the full regression suite in about one hour, and keeps coverage current automatically as your product changes, with no test rewrites, no selector maintenance, and no handoff back to your team.
FAQs
What's the difference between test coverage and code coverage in mobile apps?
Test coverage measures whether your requirements, user flows, and risk areas are actually validated, while code coverage only tracks which lines or branches executed during a run. A checkout flow can hit 100% code coverage and still ship broken if the assertions never checked whether the transaction completed correctly. Minitap handles both dimensions at once: its agent reads your app from source, maps every integration and UI scenario automatically, and tests whether user jobs actually complete, not merely whether lines ran. Chasing a code coverage number while leaving user flows unvalidated is where most mobile regressions hide.
How can my engineering team stop spending time maintaining regression tests after every UI change?
Minitap's autonomous QA agent owns the entire maintenance loop so your engineers never touch the test suite again. Instead of relying on brittle selectors that break when UI elements move, Minitap reads the running app directly and tests whether user jobs complete, so when the UI changes, the agent adapts without any human intervention. There are no selectors to rewrite, no scripts to update, and no maintenance triage blocking the next release. For teams shipping frequently with AI coding tools like Cursor or Claude Code accelerating output, that maintenance debt compounds fast, and Minitap is where it stops.
How can we run a full mobile regression suite without slowing down weekly releases?
Minitap runs the full regression suite on cloud iOS simulators and Android emulators and delivers results in approximately one hour. The agent connects to your codebase, maps every testable scenario automatically, and runs continuously against your live build, with no test scripts required from your team. When something breaks, Minitap surfaces a session recording clipped to the exact moment of failure, logs, and a fix prompt ready to paste into Cursor, all before the release ships. Teams trigger runs directly from a GitHub PR or a Slack mention of @Mini, keeping QA inside the workflow instead of outside it.
Can Minitap test both iOS and Android user journeys without maintaining two separate test suites?
Yes. A single flow specification in Minitap covers both iOS and Android simultaneously, so there is no separate suite to author or maintain per platform. Minitap's agent executes the same test goal across iOS and Android without any rewriting, running on cloud iOS simulators and Android emulators from one unified specification. This eliminates the parallel maintenance burden that doubles QA work before every new feature ships. Minitap also supports web app testing from the same platform, so teams covering mobile and web no longer need separate tooling for each.
How does an autonomous QA agent differ from a script-based testing framework like Appium or Maestro?
Script-based frameworks like Appium and Maestro require your engineering team to write every test, maintain selectors when the UI changes, and triage failures when scripts break, so the automation handles execution, but your team owns the full maintenance loop. Minitap's autonomous agent owns the entire loop: authorship, execution, maintenance, and root cause analysis, with no engineer involvement. When your UI changes, Minitap adapts without anyone rewriting a selector. When something breaks, it delivers a session recording, logs, and a fix prompt, not a broken test for your team to debug. The structural difference is that script-based tools shift maintenance cost onto engineers; Minitap removes it from the equation entirely.