
If you've ever finished an exploratory testing session feeling like you covered the important stuff, only to find a bug in production two days later, you already know the core tension. Exploratory testing is genuinely good at finding what scripts miss. The catch is that it scales with tester hours, and tester hours run out. This is where that tension leads and what to do about it.
TLDR:
- Exploratory testing combines test design and execution in real time, using charters and time boxes (30 to 90 minutes) to stay focused without scripts.
- Ad hoc testing has no structure, monkey testing uses random inputs with no learning loop, and exploratory testing sits between them with a charter and session notes.
- Use exploratory testing when a feature just shipped, requirements are shifting, or a bug fix needs a poke for related failures. Skip it for repeat regression passes.
- Mobile adds complexity: gestures, network swings, and interruptions rarely reproduce the same way twice, and 79% of users abandon an app after one or two failures.
- Minitap reads your app from source, maps all test scenarios automatically, and runs the full regression suite on cloud iOS simulators and Android emulators in about one hour with zero maintenance overhead.
What Is Exploratory Testing in Software Testing
Exploratory testing is what happens when a tester opens an app with no script in hand and lets curiosity do the driving. Instead of following pre-written steps, the tester learns the app, designs the next move, and executes it in the same breath. Each result shapes the next question: does this screen behave the same way after a slow network response, what happens if you back out of checkout halfway through.
Cem Kaner first described exploratory testing in the late 1980s, framing it as a discipline where test design and execution happen together instead of in separate phases. (For broader context on mobile app testing basics, that foundation matters here too.) The tester's judgment, not a document, decides what gets checked next, which is why scripted tests miss what nobody thought to write down.
How the Exploratory Testing Process Works
Exploratory testing runs in four stages, each feeding the next.
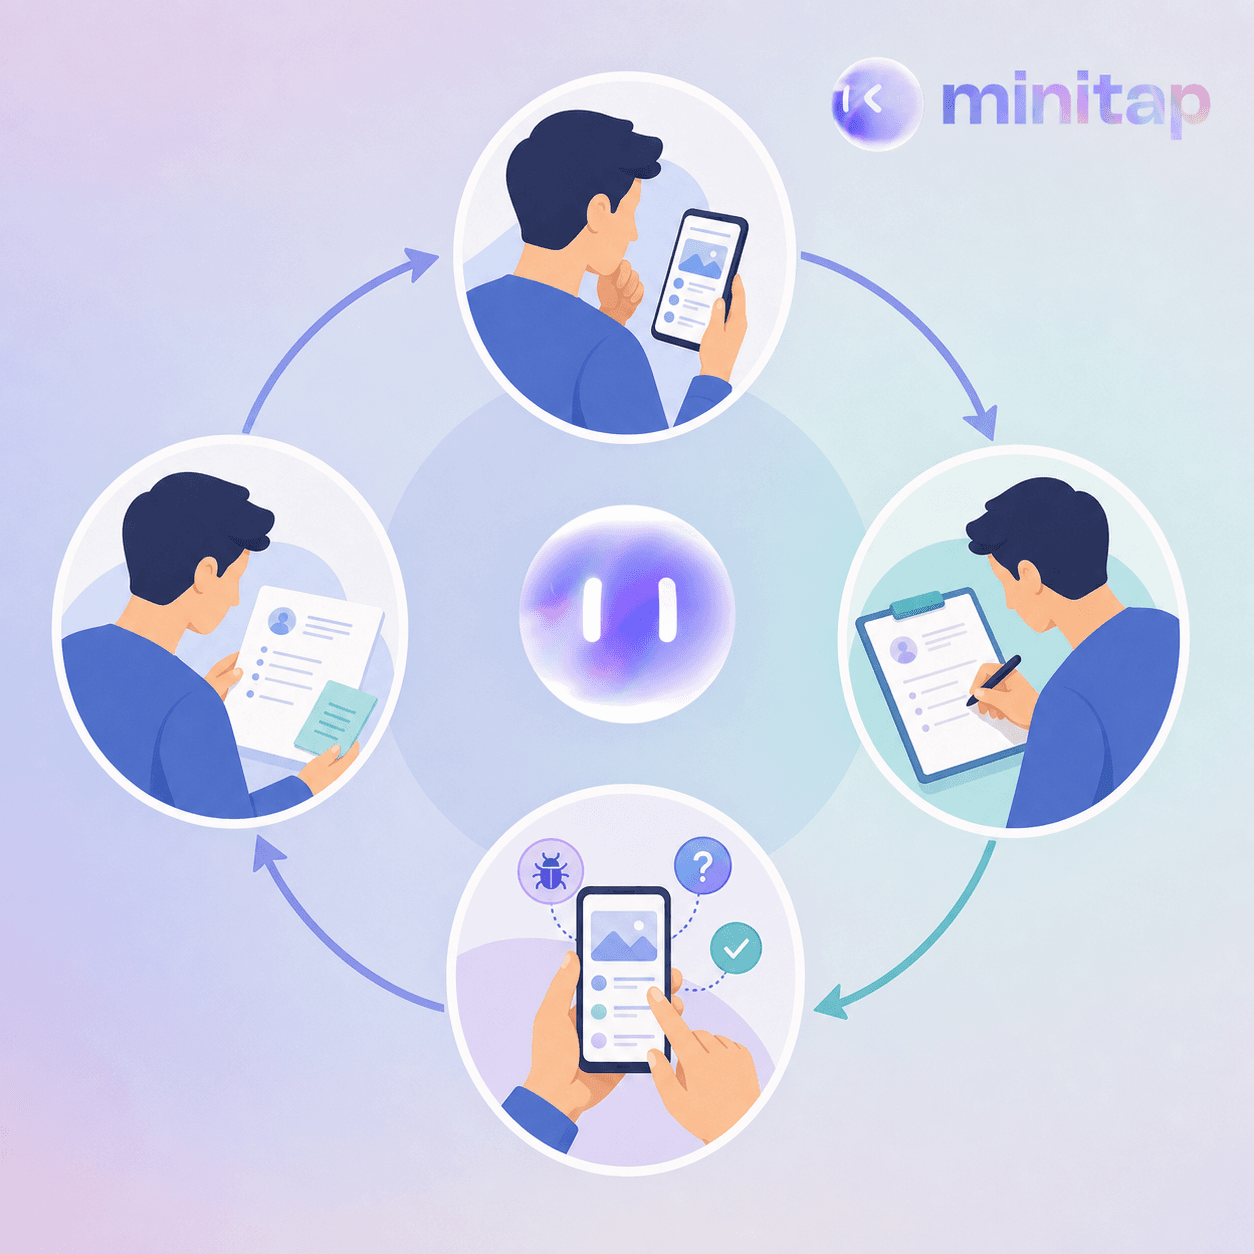
Learn the product. Before touching anything with intent, spend a few minutes clicking around, reading whatever documentation exists, and forming a rough map of what the app should do.
Define a charter. Set a mission for the session, something like "test checkout under poor network conditions for 30 minutes." A charter points the session at a goal without prescribing exact steps, complementing functional web and mobile testing that verifies defined behaviors.
Run the session and take notes. Work inside a fixed time box, usually 30 to 90 minutes, jotting down what you tried, noticed, and any bugs found. Time-boxing keeps sessions from drifting.
Debrief and decide next steps. Review notes, file bugs, and decide whether the area needs another pass, a scripted test, or nothing further.
Types of Exploratory Testing
Exploratory testing splits into a few recognizable flavors, depending on how much structure guides the session.
- Freestyle exploratory testing: The least structured variant, with no formal charter or time box, sitting closest to ad hoc testing. Best limited to quick sanity checks or a first impression of a new build before anything formal starts.
- Session-based exploratory testing: Time-boxed and charter-driven, usually 30 to 90 minutes, with notes captured throughout. This is the version most teams mean by "exploratory testing" in a sprint context. The approach pairs accountability with creative test design, which is the core idea behind session-based test management.
- Scenario-based exploratory testing: Anchored to a specific user story, like testing shipping autofill by entering a delivery location then editing it before checkout, deviating whenever something looks off.
- Strategy-based exploratory testing: Charters built around risk, spending session time on recent code changes, payment flows, or anything with a history of bugs, instead of spreading attention evenly.
Exploratory Testing Methods and Techniques
Inside a session, the charter tells you where to look. These techniques tell you what to actually try once you're there.
- Boundary value exploration: Push inputs to their edges. On a quantity field capped at 99, try 0, 1, 99, 100, and a negative number to see which ones the app silently accepts.
- User journey mapping: Walk a real path end to end, like signup, browse, add to cart, checkout, then deviate mid-path by switching payment methods after the order summary already loaded.
- Error guessing: Rely on experience to predict where bugs cluster: date pickers around leap years, file uploads with unusual formats, or forms submitted twice by double-tapping a slow button.
- State-transition exploration: Move the app between states it wasn't designed to see in sequence, such as pausing a video upload, killing the app, and reopening it to check whether the upload resumes or corrupts.
- Pairing and touring: Two testers work the same session together, one driving and one taking notes, or one tester tours the app the way a specific persona would, like a first-time user versus a power user with saved preferences.
None of these need a script. They need a tester who knows the product well enough to guess where it will break.
Exploratory Testing vs Ad Hoc Testing vs Monkey Testing
All three test without a script, which is why people mix them up. They fall on a scale from unguided to guided based on what happens before you click.
Ad hoc testing is instinct with no charter: a tester pokes at whatever seems interesting, no time box, no notes.
Exploratory testing sits in the middle, with a charter, a time box, and notes that become bug reports.
Monkey testing has no objective: random taps and inputs surface crashes, with no learning loop between what you find and what you try next.
| Approach | Structure | Goal | Output |
|---|---|---|---|
| Ad hoc | None | Quick sanity check | Informal, rarely documented |
| Exploratory | Charter, time box | Targeted learning and coverage | Session notes, bug reports |
| Monkey | None, random input | Crash and stress discovery | Crash logs, no learning loop |
Exploratory Testing vs Scripted Testing
Scripted testing writes every step before anyone touches the app: input, click, expect. It gives repeatability, so regression suites and compliance audits lean on it. Exploratory testing trades that fixed sequence for adaptability, catching what scripts miss: a confusing error message, a layout that breaks only after a specific navigation path, a field accepting input it shouldn't.
| Dimension | Scripted Testing | Exploratory Testing |
|---|---|---|
| Structure | Predefined steps | Charter-driven, adapts live |
| Repeatability | High, same steps every run | Low, sessions vary by tester |
| Documentation | Detailed test cases upfront | Session notes after the fact |
| Speed to build | Slower, requires authoring | Fast, no authorship needed |
| Defect profile | Known regressions | Edge cases, usability gaps |
Scripted tests guard known flows through regression testing for mobile apps; exploratory sessions surface what nobody thought to script. The cost, however, is that both approaches leave maintenance ownership on the engineering team. Every UI change means selector rewrites and updated test steps; every exploratory session means tester hours that don't compound. That's the gap Minitap closes: the agent reads your app from source, maps every testable flow, and runs the full regression suite in about one hour, without your team authoring or maintaining a single test script. Scripted coverage and exploratory discovery are subsumed into one autonomous loop.
Exploratory Testing in Agile Development
Agile sprints move too fast for exhaustive upfront scripting. A two-week sprint that ships a feature on day nine leaves no time to write and maintain a full test suite, and requirements often shift mid-sprint. Exploratory testing fits that rhythm because it starts the moment a build is testable.
Testers align sessions with sprint goals by writing charters straight from the sprint backlog. A story like "add saved payment methods" becomes a charter: spend 45 minutes testing add, edit, delete, and default-selection, paying attention to what happens when a user deletes their only saved card mid-checkout. During sprint review, a tester might run a similar charter against location autofill, editing the street field after autofill populates city and zip, and catch a mismatch worth logging before the next sprint planning.
Advantages and Disadvantages of Exploratory Testing
Exploratory testing earns its place for reasons that hold up under scrutiny.
Advantages:
- Uncovers defects scripted cases never anticipated, because the tester reacts to what the app actually does instead of what a document predicted.
- Adapts fast when the UI changes or requirements evolve mid sprint, since there is no script to rewrite before testing resumes.
- Uses tester expertise directly. A tester who knows where past bugs clustered spends session time there instead of spreading effort evenly.
- Generates raw material for scripted suites. Bugs found in a session often become the regression cases that catch the next occurrence.
Disadvantages:
- Reproducing a finding depends on how well the tester documented the session. Vague notes turn a real bug into a ticket nobody can confirm, a problem that compounds when flaky tests in mobile teams are already eroding trust in results.
- Coverage is bounded by one person's skill, memory, and available hours. A junior and a senior tester running the same charter will surface different bugs.
- Scaling across a large team gets messy. Ten testers running unstructured sessions in parallel duplicate effort in familiar areas and skip unfamiliar ones.
- Auditing exploratory work is harder than auditing a scripted suite, since there is no fixed step list to check against, only whatever notes the session produced.
When to Use Exploratory Testing (and When Not To)
Exploratory testing earns its keep in specific moments, not as a default habit.
Reach for it when a feature just shipped and no one has a full mental model of its behavior yet, when you need a usability read on whether a flow feels confusing or a screen reader announces things in a sane order, when a bug fix needs a poke around for siblings it might have missed, or when requirements are thin and shifting mid sprint.
It stops being the right primary tool for repeat regression passes, audit trails that demand a fixed record, or checks that must run on every commit. That is where QA automation for mobile apps runs at a pace no session can match.
Exploratory Testing for Mobile Apps: Unique Challenges
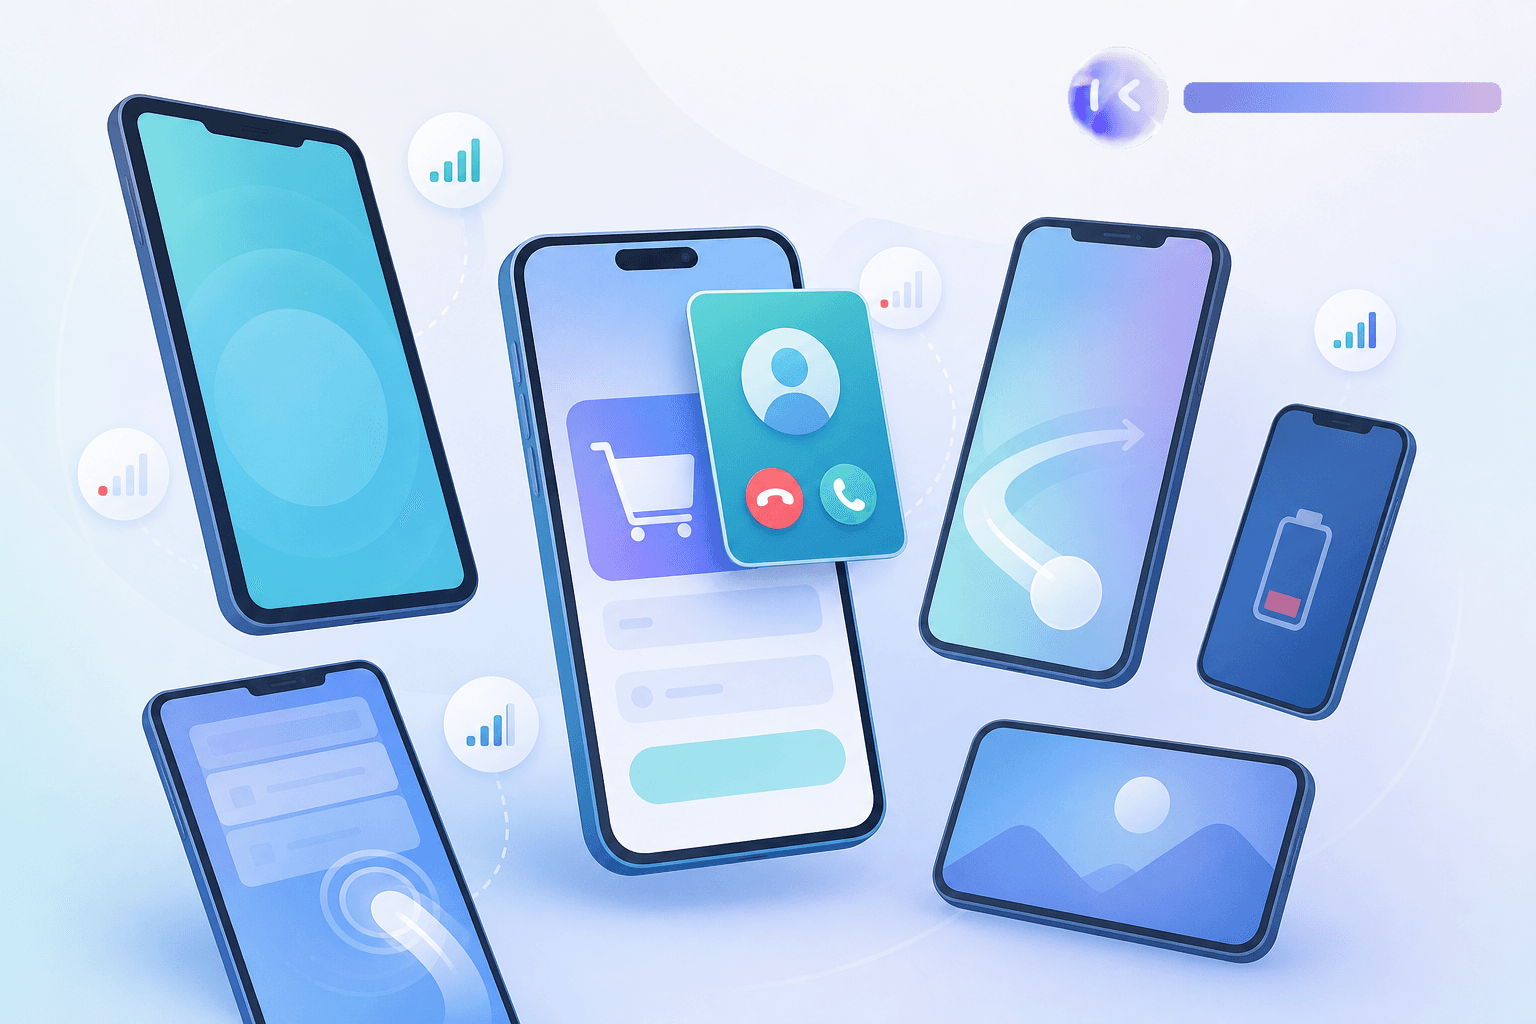
Mobile compounds everything that makes exploratory testing valuable and everything that makes it hard to scale. OS versions and screen sizes vary widely, gestures replace clicks with no DOM equivalent to anchor a script against, network conditions swing between full signal and none mid-session, and interrupts (a call, a low-battery warning, a notification sliding over checkout) rarely reproduce the same way twice. A tester running payment flows on one configuration learns little about another, which is why mobile automated testing is needed to cover the full matrix. The stakes support the effort: 79% of users abandon an app after just one or two failures, according to electroIQ. Sessions often run 30 to 45 minutes when narrowed to device-specific charters, staying inside the 30 to 90 minute range that governs any session, but scaling one sharp session across every OS, screen, and network combination is not what session-based testing was built to do.
How Minitap Extends Beyond Exploratory Testing for Mobile Teams
A session ends when the time box runs out. That's the constraint exploratory testing never escapes: coverage is bounded by how many hours a tester has and how sharp they are that day. That ceiling is exactly where a fully autonomous QA agent becomes the right answer. Minitap removes that ceiling.
Minitap is a fully autonomous QA agent that reads your app from source code, maps every integration and UI scenario automatically, and runs the full regression suite on cloud iOS simulators and Android emulators in about one hour. Where a tester writes a charter and picks a time box, Minitap exercises low-frequency flows, unstable UI paths, and edge-case scenarios no engineer would think to author, including offline and online transitions, memory conditions during active use, and in-app purchase flows tested through the RevenueCat sandbox. The agent owns the full testing loop: authorship, execution, maintenance, and root cause analysis. No engineer involvement. No loop handed back to the team.
Every run ships a session trace, screenshots, and a written explanation of each finding, with a fix prompt ready to paste into Cursor or any AI coding tool your team already uses. Engineering teams that want to stop spending time on test authorship and maintenance (whether they ship weekly or accelerate with AI-assisted development tools like Cursor) get coverage that compounds with the product instead of requiring upkeep to stay current. Web teams also get full coverage: a single Minitap agent runs across iOS, Android, and web simultaneously, so there's no separate suite to maintain per platform.
Final Thoughts on Exploratory Testing in Agile and Mobile Contexts
Exploratory testing earns its place in any sprint, and the techniques here give you a solid starting point for running sessions that actually produce useful findings. Where it stops scaling is exactly where your app's risk lives: the configurations, states, and edge cases no one thought to charter. Minitap covers that territory automatically, mapping every scenario from source and shipping a session trace, screenshots, and a fix prompt ready to paste into Cursor with each finding. See how it works for your team at minitap.ai.
FAQ
What is the difference between exploratory testing, ad hoc testing, and monkey testing?
Exploratory testing uses a charter and a time box (typically 30 to 90 minutes) to guide a targeted session, with notes that become structured bug reports. Ad hoc testing is unstructured investigation with no charter and no documentation. Monkey testing sends random inputs at the app with no learning loop between what breaks and what you try next. Only exploratory testing produces session notes and actionable findings; the other two leave no structured record your team can build on.
How can my engineering team stop spending hours on manual regression testing every release?
Minitap's autonomous QA agent eliminates manual regression testing by reading your app from source, mapping every integration and UI scenario automatically, and running the full regression suite on cloud iOS simulators and Android emulators in about one hour, with zero test authorship or maintenance required from your team. Where manual regression burns days of senior engineering time every release cycle, Minitap runs continuously between releases, surfaces failures with a recording clipped to the exact moment of breakage, and delivers a fix prompt ready to paste into Cursor. Your engineers stop touching the test suite entirely.
Can Minitap test both iOS and Android apps without maintaining separate test suites?
Yes. Minitap runs a single flow specification across both iOS and Android simultaneously, so your team never writes or maintains separate platform-specific test suites. The agent reads your codebase directly, maps scenarios for both platforms automatically, and executes them on cloud iOS simulators and Android emulators in the same run. Coverage holds through UI redesigns because the agent adapts to changes without selector rewrites or script updates, no human intervention required.
How does an autonomous QA agent work compared to scripted automation tools like Appium or Maestro?
Script-based automation frameworks execute predefined steps using selectors tied to specific UI elements. Your team writes the tests, which means your team also owns them: every UI change means selector rewrites, every new flow means new scripts, and every flaky failure means triage work that pulls engineers away from shipping. Appium, Maestro, and similar tools automate execution but leave loop ownership entirely with the engineering team. Minitap's autonomous agent works differently at the architectural level: it reads your app from source, tests user job completion (for example, "can a user log in and reach the home screen?") instead of individual UI interactions, and adapts when the UI changes, without any input from your team. The agent owns the entire testing loop: authorship, execution, maintenance, and root cause analysis. Mobile environments have no DOM equivalent, which makes selector-based testing especially brittle on iOS and Android, and the agent-based approach removes that fragility entirely.
How do we keep regression tests in sync with our codebase when we ship every week?
Minitap keeps the test suite in sync automatically when code changes, with two modes: full auto (Mini updates tests post-merge without any input) or gated (Mini proposes changes in the PR before merge so a human can validate). Either way, your team does not rewrite a single test when flows evolve or UI elements move. For teams shipping weekly or faster, Minitap also supports Run Affected: re-running only the scenarios a PR touches in one click directly from the PR, so the feedback loop stays fast without running the full suite on every commit.
What does Minitap surface when a test fails, and how does the team act on it?
When Minitap detects a failure, it delivers a severity assessment, a session recording clipped to the exact moment the issue appeared, and a fix prompt packaged with the failing criterion, observation, screenshot, and commit context, ready to paste directly into Cursor or any AI coding tool your team already uses. Failures are routed to a triage inbox with a defined lifecycle (Needs Review → Acknowledged → Resolved) and posted as Slack alerts with an inline video so the team can watch, triage, and act without opening a separate platform. Engineers see exactly what broke, where it broke, and how to fix it, without owning or investigating the test infrastructure themselves.