
Every release cycle your team runs the same manual tests, catches the same categories of regressions, and talks about automating more of it next quarter. The problem is not conviction. The problem is knowing which tests belong in the automated suite and which ones cost more to maintain than they are worth. You need a decision framework that accounts for failure frequency, UI stability, and business impact before you write a single line of test code. That framework is what this walks through.
TLDR:
- Automate tests that run repeatedly and cover stable flows like login, checkout, and onboarding first.
- Maintenance cost grows with coverage: teams with high automation sometimes spend more time fixing tests than writing new ones.
- Keep exploratory testing, usability review, and low-frequency flows manual until behavior stabilizes.
- Flaky tests destroy trust in your suite when engineers ignore failures and merge anyway.
- Minitap is a fully autonomous QA agent: the agent self-heals when UI changes and ships a session trace, screenshots, and written findings with every run.
The Case for Test Automation: When Investment Pays Off
Test automation pays off when the math works in your favor. The core question is whether the time saved across repeated test runs exceeds the time spent writing, maintaining, and fixing the tests themselves.
A regression suite that takes four hours to run manually but fifteen minutes automated delivers compounding returns every release cycle. Run it weekly and you recover that time fifty times a year. SmartBear's ROI measurement guide covers measurement approaches in detail; the two key factors are execution time saved versus maintenance overhead added. The calculus flips when tests are fragile, rarely run, or cover flows that change constantly.
Three conditions generally signal automation is worth pursuing:
- The test covers a flow that ships repeatedly without changing its core behavior, such as login, checkout, or onboarding.
- The failure cost is high enough that catching it manually, after the fact, creates real business damage.
- The team has enough runway to maintain what they build, because an unmaintained suite drifts into noise faster than most teams expect.
When those conditions aren't met for a given flow, Minitap handles it without requiring your team to build or maintain anything.
Understanding Test Types and Their Automation Potential
Not every test type responds equally well to automation. Understanding where automation adds value and where it creates busywork is the foundation of any sound decision framework.
Here are the four core test types and how they map to automation potential:
- Unit tests are the clearest automation win. They run fast, produce deterministic results, and require no UI interaction. Mobile application testing frameworks provide the foundation for building these automated tests. If your unit tests are still running manually, that's the first thing to fix.
- Integration tests automate well once your environments are stable. The catch is flakiness tied to network state, seeded data, or service dependencies. Solve for environment consistency first, or you'll spend more time debugging test failures than actual bugs.
- End-to-end tests are where automation decisions get complicated. High-value, stable flows like login, checkout, and onboarding are strong candidates. Flows that change frequently or depend on third-party UI are poor candidates until they stabilize.
- Exploratory testing on shifting UI is where script-based tools break first. Writing stable selectors against an interface that changes every sprint means rewriting tests as often as the feature ships. Minitap's agent adapts to UI changes without selector rewrites, so coverage continues even while the surface evolves.
The pattern here is consistent: automate what is stable, high-frequency, and well-defined. For flows that are still shifting or judgment-dependent, Minitap's agent covers them without requiring your team to encode every rule upfront.
Tests That Should Be Automated First
Start with your highest-confidence, highest-frequency flows. Login, checkout, account creation, core navigation. These run every release, fail in ways that block every other test, and take the longest to verify manually. Automate them first.
After that, look at anything your team reruns more than twice per sprint. Repetition is the signal. If a human is running the same sequence on every build, that sequence belongs in your test suite.
A few categories surface repeatedly across mobile and web teams:
- Regression on critical user paths: flows that, if broken, generate immediate user-facing failures like checkout errors, login loops, or broken onboarding that stops new users before they see the product.
- Form validation and input handling: required field checks, character limits, and error state display that teams tend to verify manually but rarely change structurally.
- API contract verification: confirming that request and response shapes match what the client expects, for example, a
/loginendpoint that starts returning a numeric user ID where the client expects a string will break the UI silently until a contract test catches it before deploy. - Session and auth state: token storage, refresh flows, and logout behavior are tested inconsistently by hand and fail in ways that are hard to reproduce without a controlled environment.
For flows still in flux, new features with shifting UI, exploratory passes on unreleased behavior, anything that requires judgment about whether the experience feels right, Minitap handles those runs without your team writing or maintaining test scripts for them.
Where Script-Based Automation Breaks Down
Script-based tools break in predictable places. The UI, selectors stop matching, and the test suite goes red for reasons that have nothing to do with the app's behavior. These are the categories where scripts fail, and where Minitap's autonomous agent picks up coverage without requiring your team to rewrite anything.
A few categories consistently belong in human hands:
- Shifting UI on new features: scripts tied to element IDs or class names break every sprint as the interface evolves. Minitap's agent adapts to UI changes without selector rewrites, so coverage holds through redesigns.
- Usability and accessibility review: questions about whether something reads clearly or meets standards require contextual interpretation. Minitap's session traces and written findings give your team the context to make those calls without re-running tests by hand.
- Low-frequency flows: flows that run once per cycle are expensive to script and maintain. Minitap covers them as part of full-suite execution without additional setup cost per flow.
- Biometric and system-level prompts: camera input, biometric gates, and hardware peripherals fall outside script-based frameworks. Minitap runs against cloud iOS simulators and Android emulators, handling system-level interactions that most scripted frameworks cannot reach reliably.
The rough heuristic for scripts: if a test requires subjective evaluation or covers a surface that changes faster than selectors can be updated, scripts fail faster than they help. Minitap removes that constraint by owning maintenance itself.
The Hidden Cost of Test Maintenance
Test automation sounds like a cost-reduction story until you price in what it takes to keep tests passing.
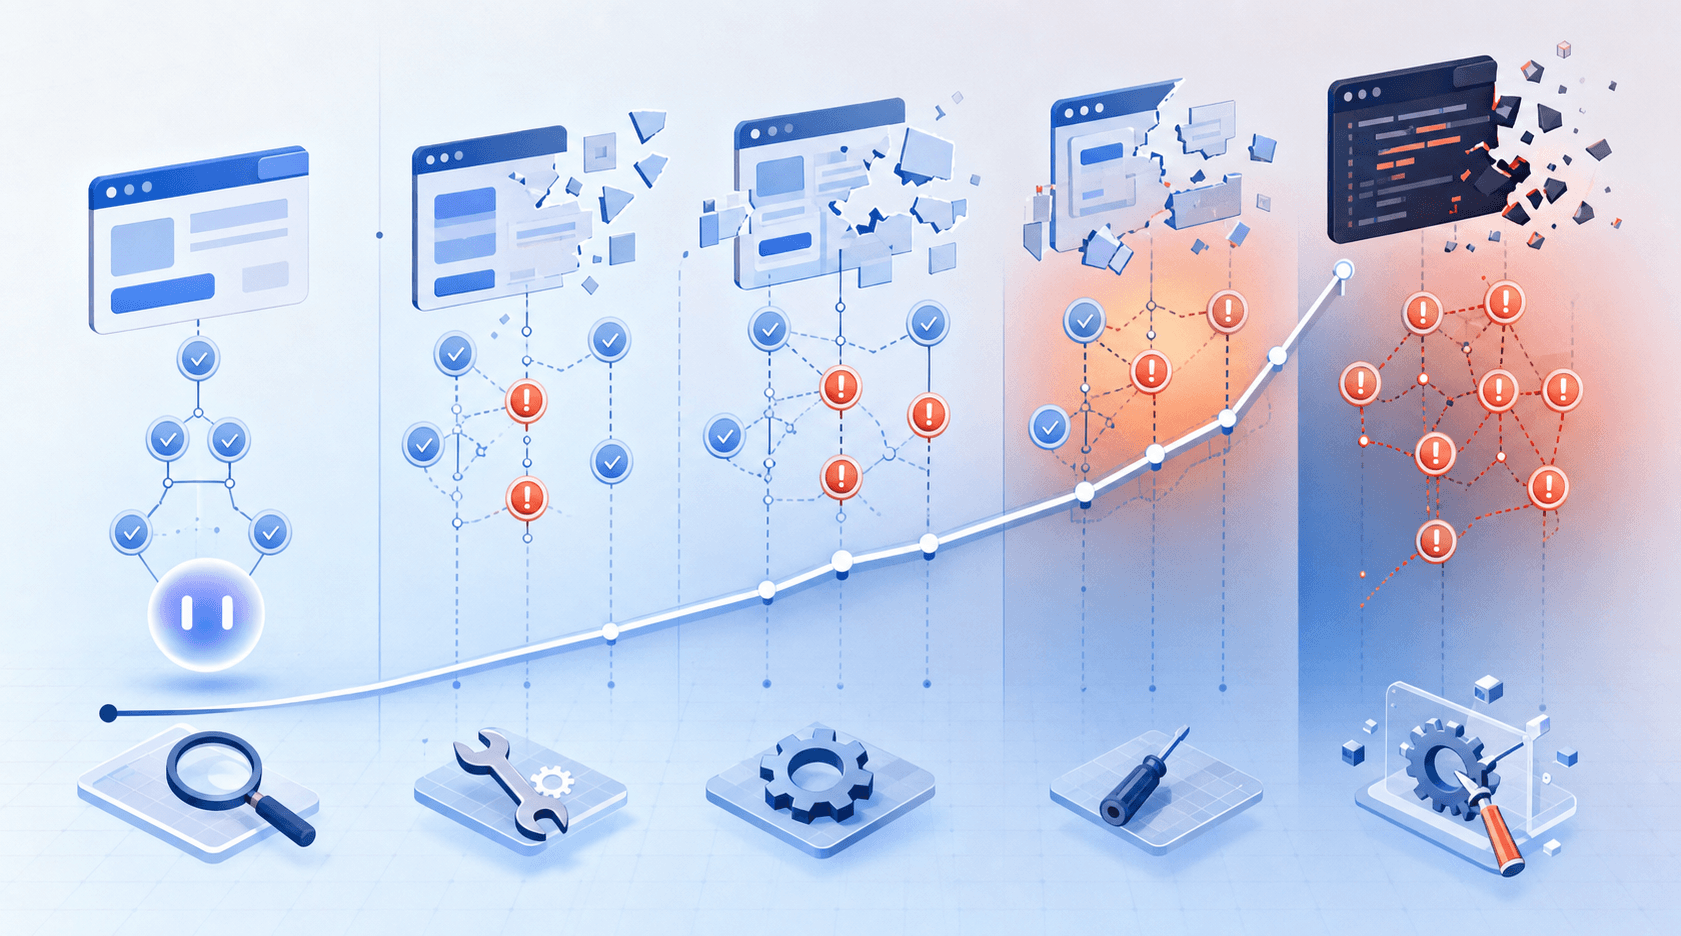
Scripts break when the UI changes. Selectors drift. A button gets renamed, a screen gets restructured, and suddenly 40 tests are failing for reasons that have nothing to do with the app's behavior. Someone has to triage that, and it's usually a senior engineer.
The maintenance burden tends to grow in proportion to coverage. The more tests you write, the more surface area you own. Teams running large automated suites, in some cases hundreds of tests, can find themselves spending more time fixing broken tests than writing new ones.
Three failure patterns surface repeatedly:
- Selector fragility: tests tied to element IDs or class names that change with every design iteration, requiring manual updates after each UI release cycle
- Environment drift: tests written against one API state that fail silently when staging and production configs diverge, producing false negatives that erode trust in the suite
- Flakiness accumulation: timing-dependent tests that pass locally but fail in CI, where teams spend hours chasing failures that reproduce inconsistently and never get fully resolved
The decision to automate a test is also a decision to maintain it. In practice, maintenance cost is the most commonly underestimated factor at the start of an automation program.
Mobile Testing: Why the Decision Calculus Changes
Mobile apps fail in ways web apps rarely do. A test that passes in a clean environment may fail when the app has been running for several hours with low memory and other processes competing in the background. Understanding these mobile application testing challenges is critical for building reliable automation. iOS adds its own surface area: App Store review cycles, strict sandboxing rules, and framework-specific testing constraints.
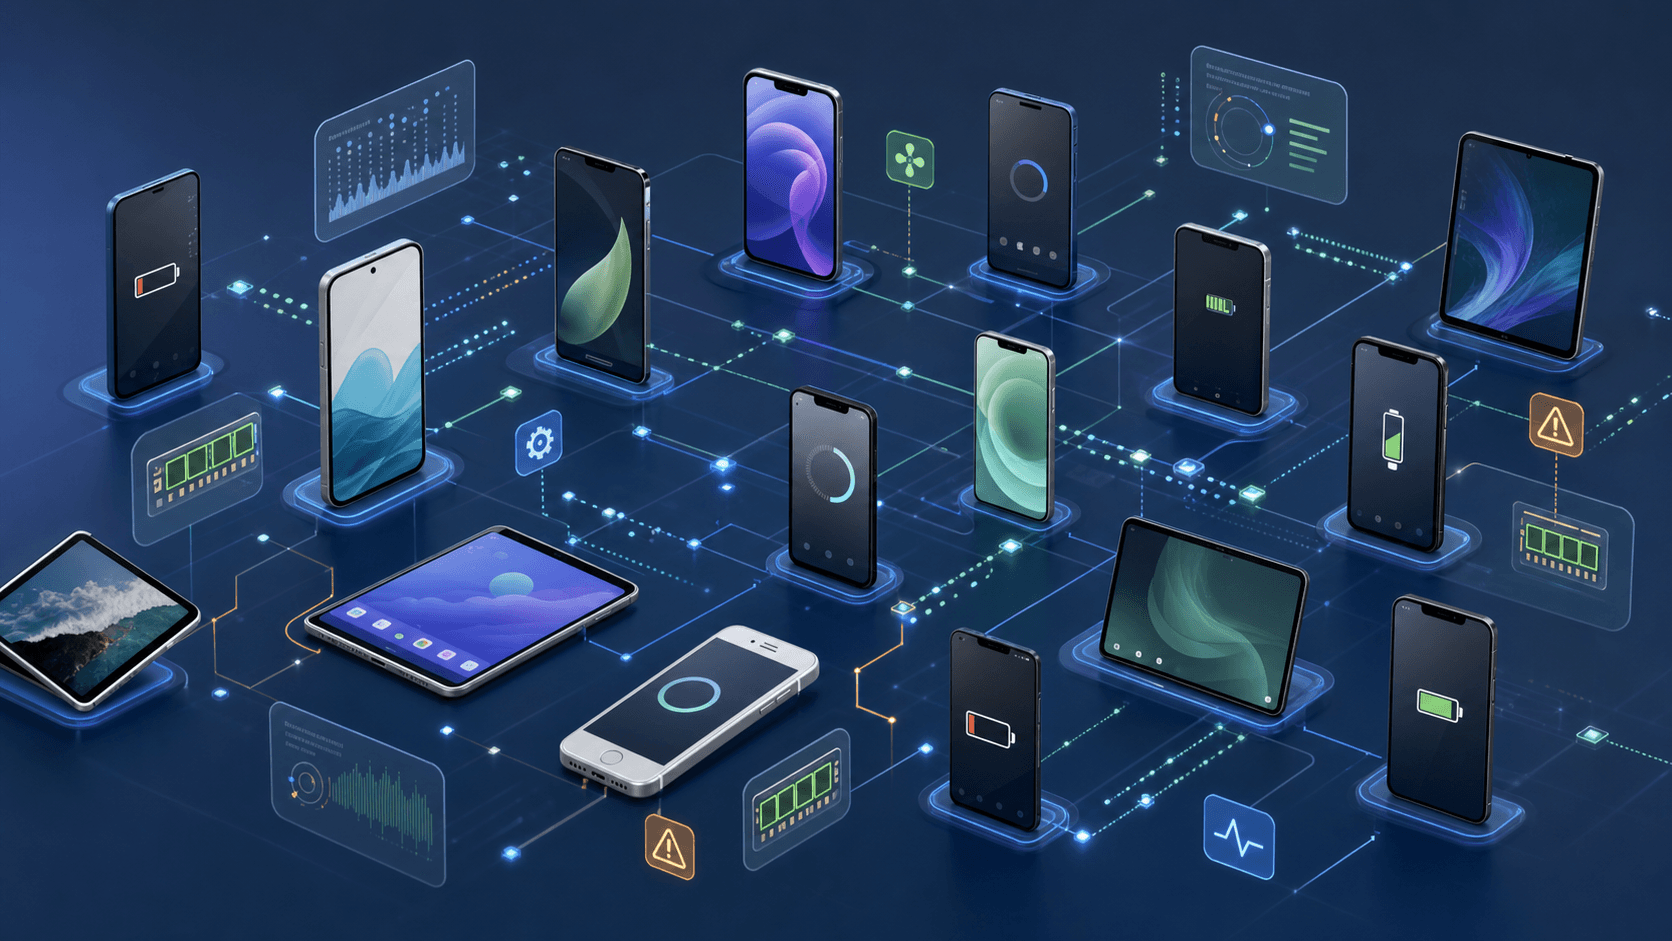
None of that changes what you're testing for. Minitap's agent runs against cloud iOS simulators and Android emulators, handling the state variability and environment conditions that break scripted tests, and delivers results without your team managing the infrastructure.
Flaky Tests and the Erosion of Trust
Flaky tests don't just slow your pipeline. They quietly destroy confidence in the entire suite. When engineers see a red build, check whether it's "probably just flakiness," and merge anyway, your test coverage has already stopped working as a signal.
Microsoft engineering has documented the productivity impact of flaky tests, citing misleading quality signals as a key driver of developer time lost to false failures.
The failure mode compounds. A test that intermittently fails gets skipped, disabled, or ignored. Over time, the suite runs but nobody trusts what it's telling them. That gap between coverage on paper and coverage that actually catches regressions is where production bugs get through.
The root causes are usually a short list:
- timing dependencies and UI element readiness before the app has finished drawing it
- Shared state between test runs that leaves the environment in an inconsistent condition
- Network calls that return different results across runs due to latency or test data drift
- Animations or transitions that block interactions the test expects to complete instantly
Fixing flakiness isn't a cleanup task. It's a prerequisite for knowing whether automation is working at all.
Building a Decision Framework: Risk, Frequency, and Stability
Three questions determine whether a test case belongs in your automation suite.
- Does this flow break often enough that manual checking is a recurring cost? Login, checkout, and onboarding fail regularly under real conditions and catch regressions that matter.
- Is the behavior stable enough that a test written today will still be valid next sprint? Automating a UI in active redesign means rewriting tests as fast as features ship.
- What's the cost if this breaks in production? A payment failure reaching users costs real revenue. A low-traffic settings screen failing quietly costs almost nothing.
Run each candidate through all three questions and score it 1 to 3 on each factor (1 = low, 3 = high). Tests scoring 7 or above are your first automation targets. Scores between 4 and 6 are candidates to defer until behavior stabilizes. Scores of 3 or below belong in Minitap's queue, not a script.
A quick example: the checkout flow breaks regularly (3), the UI has not changed in three sprints (3), and a failure costs real revenue (3). Score: 9. Automate it now. A new onboarding screen ships every sprint (UI stability: 1), rarely breaks in a way users notice (failure frequency: 1), and a failure affects a small share of new users (impact: 2). Score: 4. Let Minitap cover it until the feature stabilizes.
Low stakes, low frequency, or unstable UI is where scripts break down. Minitap covers those flows without requiring your team to maintain them.
| Factor | Script Automation | Use Minitap |
|---|---|---|
| Failure frequency | Breaks regularly | All flows, any frequency |
| UI stability | Stable across releases | Stable or actively changing |
| Business impact | Revenue or retention risk | Any, agent owns maintenance |
Minitap: Fully Autonomous Mobile QA Agent That Eliminates the Maintenance Burden
Minitap is built around one structural bet: the maintenance burden that limits most automation programs should belong to the agent, not your team.
Here is how it works in practice. Minitap agents run your critical user flows and self-heal when the UI changes, learn more about how Minitap AI agents work.
What you get back is coverage that grows with your app without accumulating maintenance debt. Every release expands the suite instead of breaking it.
Works for any engineering team that ships mobile. The agent owns test authorship and maintenance whether you run a dedicated QA function or engineers cover quality alongside product work. Coverage runs every release and grows with your app.
Every run ships a session trace, screenshots, and a written explanation of each finding. When comparing mobile application testing services, Minitap stands apart: the agent owns authorship and maintenance while giving full visibility into every test outcome. No maintenance overhead, no opacity.
Bottom line: Minitap fits any engineering team that ships mobile. The agent owns test authorship, selector maintenance, and flake resolution so your coverage runs every release without adding to your team's load.
Final Thoughts on What Belongs in Your Automated Test Suite
You automate the tests that run repeatedly, cover stable flows, and catch failures expensive enough to outweigh the maintenance cost. Login, checkout, onboarding. Anything your team reruns more than twice per sprint. Minitap covers the rest: unstable UI, low-frequency flows, and exploratory passes, all without your team writing or maintaining anything. The agent owns the full QA loop so your coverage grows with every release.