
You need shorter enterprise regression cycles across web and mobile apps, browsers, and feature flags, beyond iOS and Android test execution alone. Minitap is an AI QA employee that writes and runs tests, proposes updates when the app changes, and provides reviewable run evidence. Some tools run flows your team describes; others generate scenarios from product context and take on routine maintenance. Our November 2026 ranking of autonomous QA agents for iOS and Android starts with that ownership gap, then checks documented mobile support and reviewable findings, so you can choose based on the work each agent actually takes over.
TLDR:
- Compare who writes and maintains your mobile tests before comparing execution speed.
- Verify native iOS and Android coverage. Web testing alone does not cover mobile flows.
- Check where failures reach your developers and whether reports include run evidence.
- Rankings use public vendor documentation, not internal benchmark testing.
- Minitap writes and runs tests across iOS, Android, and web, and proposes updates when the app changes.
What Are Autonomous QA Agents for iOS and Android Apps?
Autonomous QA agents take on test authorship, execution, and maintenance for iOS and Android apps. They interpret expected behavior and run functional tests on real interfaces. With script-based frameworks such as Appium, Espresso, and XCUITest, engineers handle QA automation for mobile apps by writing test logic and updating it as the app changes.
The deciding question: who owns that ongoing work? Minitap is an AI QA employee that writes scenarios with acceptance criteria, tests what appears on screen across web and mobile, and proposes updates when expected behavior changes.
How We Ranked Autonomous QA Agents for Mobile
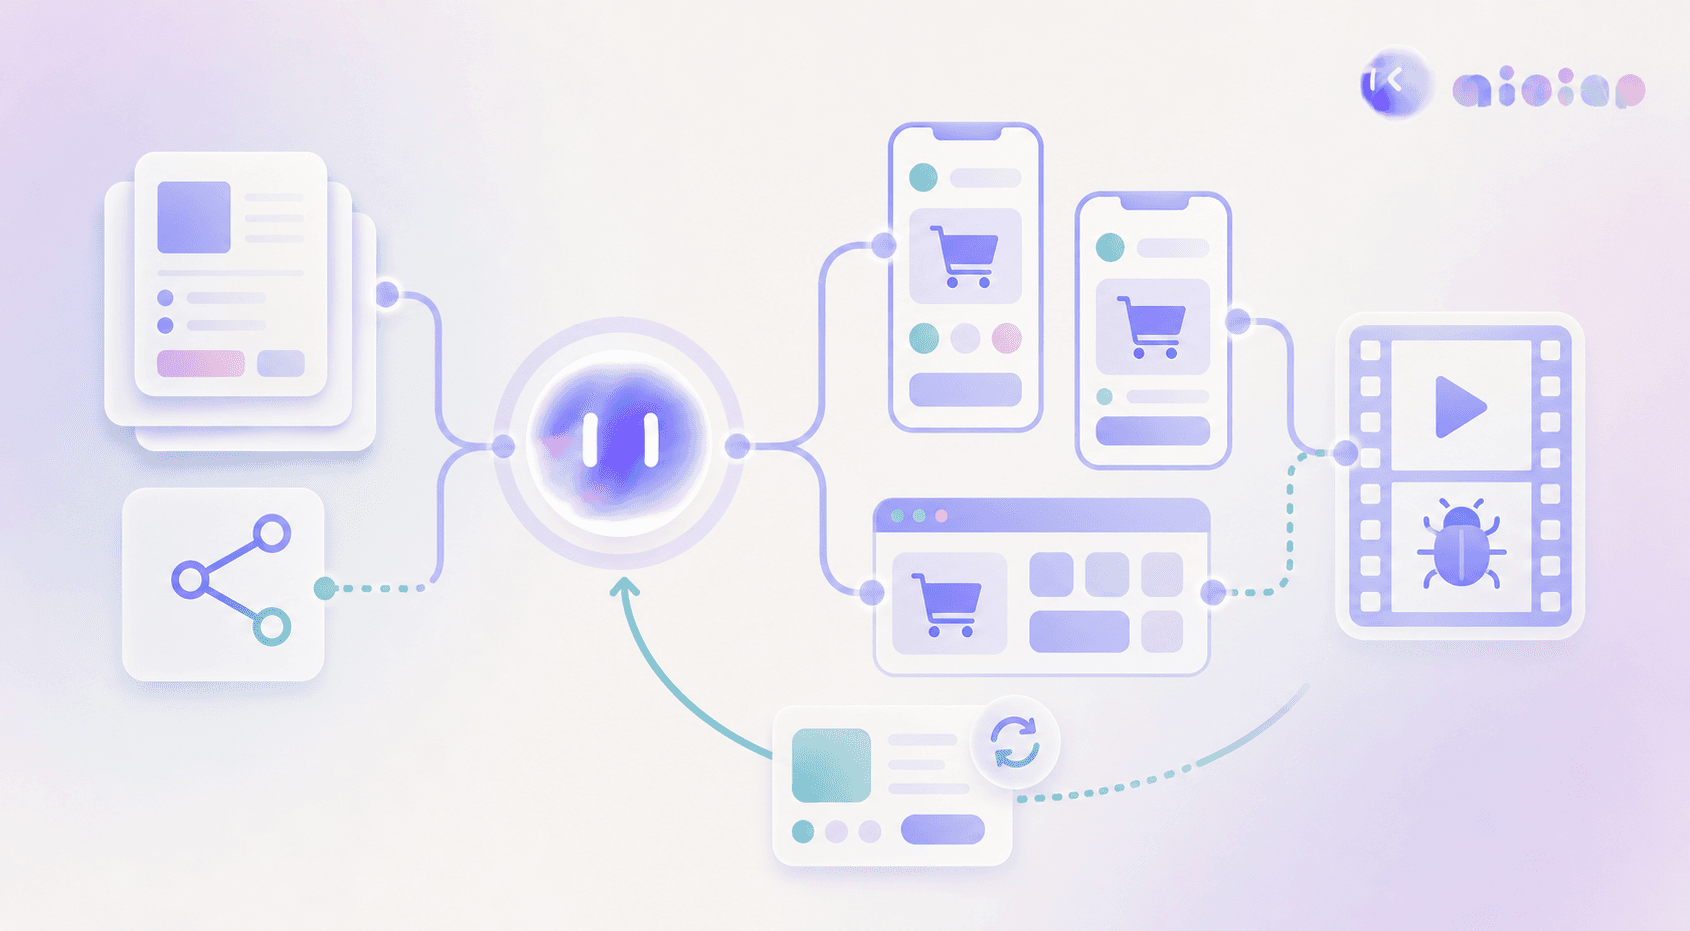
We ranked autonomous mobile QA agents using public vendor information and documented capabilities, not internal benchmark testing at Minitap. Maintenance ownership came first. Our criteria were:
- Who writes tests and maintains them after app changes.
- Documented coverage across iOS, Android, and web.
- Failure investigation capabilities and evidence included in bug reports.
- Integration with CI/CD, pull request tools, and AI coding assistants such as Cursor.
- Documented runtime diagnostics, including memory and CPU monitoring.
Undocumented capabilities remained unverified. Broad AI testing claims alone did not count as evidence.
Best Overall Autonomous QA Agent for iOS and Android: Minitap
Minitap is an AI QA employee that writes tests and proposes updates when the app changes. It runs black-box visual regression tests across iOS, Android, and web without team-authored scripts.
- Scenarios draw on product requirements, specs, and tickets; the GitHub repository helps draft and maintain them, and verdicts come from the screen.
- Blockers surface with recommended next steps, including review where needed.
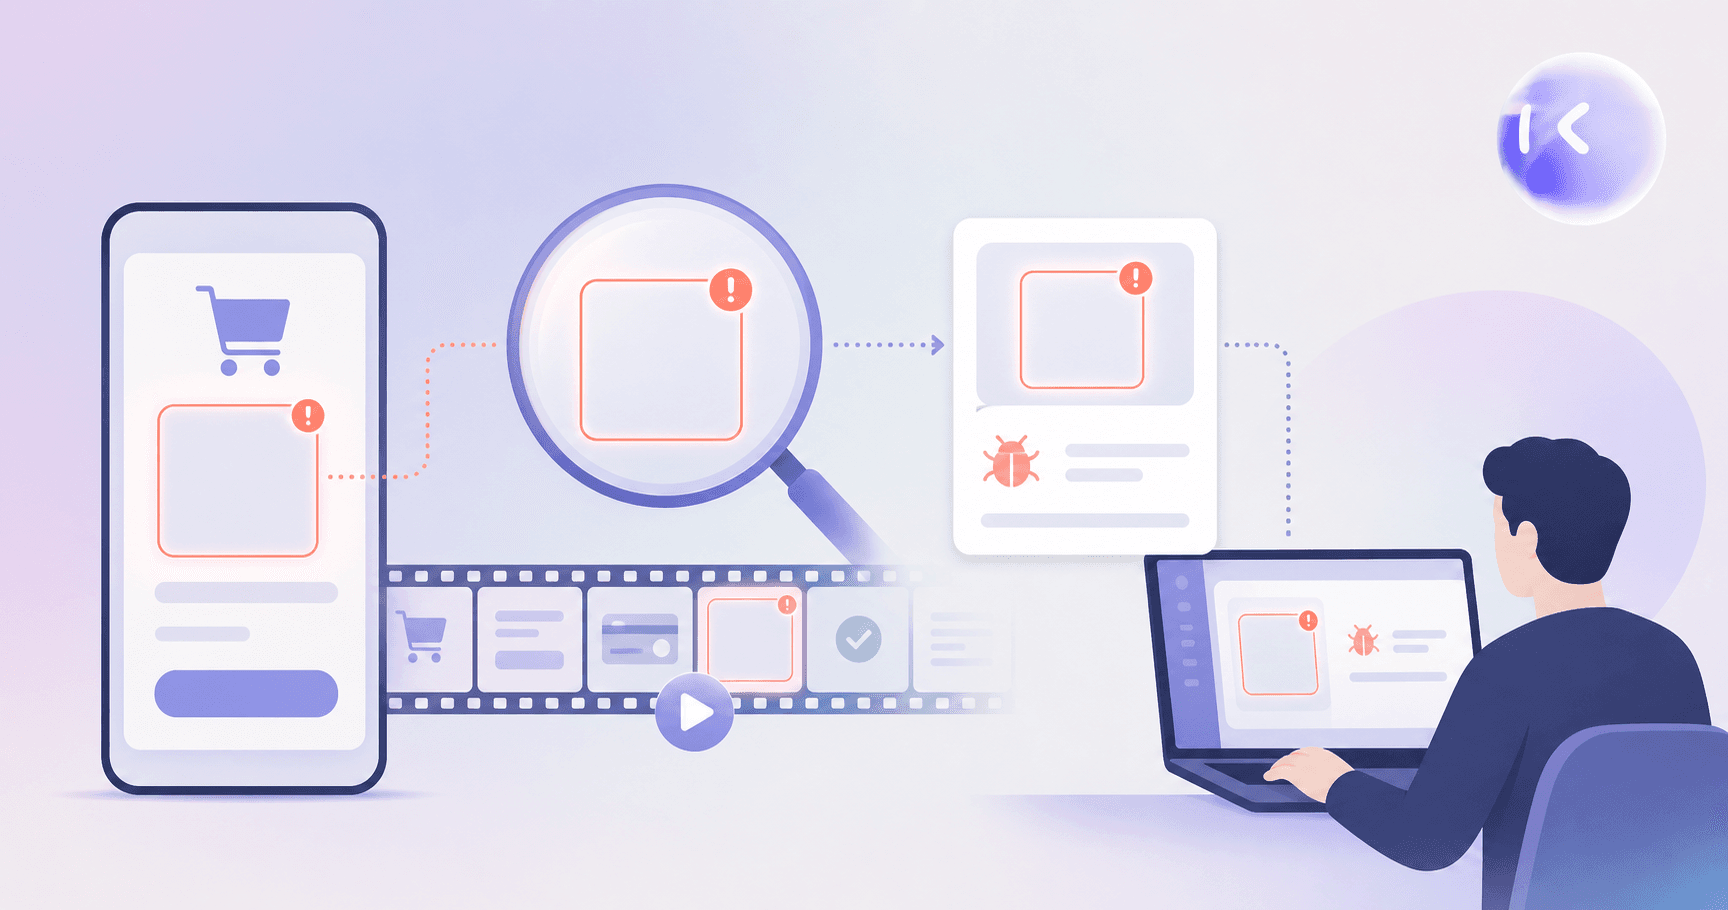
- Findings include run video and actionable bug reports.
- mobile-use, Minitap's separate open-source research project, was the first to solve the AndroidWorld benchmark completely, completing all 116 tasks. This result belongs to mobile-use, not the Minitap product.
Bottom line: Minitap removes script maintenance and provides reviewable evidence for release decisions.
QA.tech
QA.tech runs AI-agent tests from plain-language instructions, for web apps and for native iOS and Android apps.
What They Offer
According to QA.tech's documentation, the same AI agent that powers its web testing also tests native iOS and Android apps, on cloud-hosted iOS simulators and Android emulators. Mobile testing is enabled per organization, and real-device testing is listed as coming soon.
- Teams create and edit tests in natural language through QA.tech's chat assistant.
- A GitHub pull request review runs on preview URLs, including Vercel previews behind deployment protection. For native apps, CI uploads the PR build and pins the review to it.
Good for
QA.tech fits teams that want natural-language tests across web and mobile and already work with pull-request previews. Its change review can select relevant tests from a diff, while the team keeps defining the journeys and expected results that matter for a release. The ownership check is concrete: assign someone to describe new flows as features ship, and verify who updates expected behavior when the product changes.
Limitation
Mobile runs use cloud simulators and emulators today; QA.tech lists physical devices as coming soon. Native PR testing needs a CI step that uploads each build. Before counting QA.tech toward mobile regression, run one release-critical native journey, such as a one-time-password login or an in-app purchase restore, on your own builds.
Bottom line
QA.tech covers web and native mobile with natural-language tests, and your team keeps describing the journeys and expectations. Minitap writes scenarios and proposes routine updates across iOS, Android, and web. It turns product specs, tickets, and existing test cases into scenarios with acceptance criteria, then checks expected behavior against what appears on screen. When the app changes, Minitap proposes scenario updates instead of leaving engineers to rewrite test scripts. Run videos and actionable bug reports give your team evidence to review.
Drizz
With Drizz, your team writes the tests.
What They Offer
Drizz offers Vision AI mobile testing:
- Plain-English instructions and self-healing automation.
- Execution on real devices, emulators, and simulators, for iOS, Android, and mobile web.
- On-prem or VPC deployment, SSO/SAML, and audit logs on its Team plan, according to Drizz.
Good for
Drizz targets QA-led teams that retain responsibility for writing and updating test instructions and require physical-device execution. Its plain-English authoring model aligns with teams that already have defined mobile regression journeys and QA owners who can specify steps and expected results. Real devices, emulators, and simulators provide the execution setting; confirm that your required builds and device configurations are supported during a pilot. For example, have the team describe a checkout journey, run it on the required devices, then repeat after a UI change to check what self-healing handles and which instructions still need revision. That fit depends on continued authorship capacity: new features and changed expectations still require someone to update the described flows.
Limitation
Teams write and update steps. Compared with other mobile application testing frameworks, Drizz documents mobile web but not desktop web, so confirm browser coverage if your journeys start on desktop.
Bottom line
Drizz reduces execution and maintenance work through visual self-healing, but your team still writes the instructions and updates them when expected behavior changes. Minitap writes scenarios and proposes routine updates across iOS, Android, and web. It turns product specs, tickets, and existing test cases into scenarios with acceptance criteria, then checks those expectations against what appears on screen. When the app changes, Minitap proposes test updates; when a run is blocked, it explains the blocker and recommends the next action. Run videos and actionable bug reports give your team evidence for release decisions without requiring engineers to write and repair test scripts.
Spur
Your team authors Spur’s tests; coverage follows what people describe.
What They Offer
Spur documents native mobile QA on cloud iOS simulators and Android emulators, alongside web testing:
- Plain-English test steps, with no code, selectors, or test IDs.
- Uploaded simulator and emulator builds for native apps.
Good for
Spur fits teams that retain ownership of test descriptions and updates, including nontechnical QA and product owners. Its plain-English authoring model suits QA managers and product teams that can specify customer journeys and expected results without writing scripts. For a pilot, describe a shopper selecting a product variant, adding it to the cart, applying a discount, and completing checkout, then verify the outcome at each step. The ownership check comes after a change: revise a promotion rule or checkout step and measure how much work the team needs to keep those descriptions current.
Limitation
As with many AI software testing tools, confirm CI support, repository hosting, and runtime monitoring for your pipeline during the pilot.
Bottom line
Spur automates execution, but your team still owns the plain-English test descriptions and updates them when expected behavior changes. Minitap writes scenarios and proposes routine updates, using repository context, product specs, tickets, and existing test cases to draft scenarios with acceptance criteria. It runs those scenarios as black-box visual tests across iOS, Android, and web, grounding findings in what appears on screen instead of inferring success from source code. When the app changes, Minitap proposes test updates; when execution is blocked, it explains why and recommends the next action. Run videos and actionable bug reports let your team review what happened without reconstructing the failure or maintaining test scripts.
MobileBoost
MobileBoost leaves refinement and validation with your team. Its mobile AI SDET, backed by Y Combinator, generates native XCUITest and Espresso test code from natural language or pull-request changes, runs iOS and Android tests, and updates code after app changes.
What They Offer
- Native XCUITest and Espresso test code.
- Simulator and physical-device execution.
Good for
MobileBoost targets enterprise mobile teams that retain responsibility for refining generated tests and validating maintenance updates, including those testing vibe coded apps. Its plain-language generation suits workflows where QA analysts and engineers already define expected outcomes and review test logic before adding it to regression runs. Simulator and physical-device execution support teams checking iOS and Android builds. For a pilot, supply a checkout specification, review whether the generated test verifies the cart total and order confirmation, then repeat after a checkout change. Track which updates MobileBoost handles and which need team adjustment: the fit depends on having owners for refinement and validation; access to AI-generated tests alone is not enough.
Limitation
Your team still refines generated tests and validates maintenance updates, so automated code changes do not remove ongoing ownership. MobileBoost's public documentation does not mention web testing; treat browser coverage as unverified instead of assuming iOS and Android support extends to web. For a product with a shared account or checkout journey, a passing native test does not confirm that the equivalent browser flow works. Ask MobileBoost to show that browser journey before counting it toward cross-platform regression coverage. During the same pilot, change an expected checkout result and track which generated assertions your team must review or adjust before the updated test is ready to run.
Bottom line
MobileBoost generates and updates mobile test code, but your team still owns refinement and validation of those changes. Minitap writes scenarios and proposes routine updates, turning product specs, tickets, and existing test cases into scenarios with acceptance criteria. It runs those scenarios as black-box visual tests across iOS, Android, and web, checking expected behavior against what appears on screen. When the app changes, Minitap proposes test updates and surfaces only the changes it cannot settle on its own for review with context. Run videos and actionable bug reports give your team evidence for release decisions without requiring engineers to rewrite test scripts.
Panto AI
Teams write Panto AI’s flow descriptions and confirm healing updates. Panto converts those descriptions into automated mobile tests.
What They Offer
- Physical-device execution with UI self-healing.
- SAST scanning, code review, and memory, CPU, FPS, and startup metrics.
Good for
Panto AI targets mobile QA teams that retain flow authorship and review self-healing updates while assessing security scanning in the same platform. Its bundled SAST scanning and code review serve a separate need from functional testing: a passing user journey does not confirm that the underlying implementation is secure. Physical-device execution and memory, CPU, FPS, and startup metrics give teams additional checks to assess alongside the flows they describe. For a pilot, describe a login journey with explicit success and failure outcomes, run it against an uploaded build, and review functional results separately from security findings. Then change the login UI and check which healing updates need confirmation, so the evaluation captures ongoing QA work beyond the first successful run.
Limitation
Your team still writes flow descriptions and confirms self-healing updates, so changes to expected behavior remain an ongoing QA responsibility. Panto AI requires APK/IPA uploads for mobile execution; include build preparation and upload handling when assessing its release workflow. The available description does not confirm source-based scenario generation, so do not treat its bundled code review as evidence that it identifies test journeys from your repository. Web testing also remains outside the mobile coverage described here: a passing in-app checkout does not validate the equivalent browser purchase. During a pilot, change a checkout requirement and track which flow descriptions and healing updates your team must revise or approve before counting the regression run as complete.
Bottom line
Panto leaves flow authorship with your team, raising the question of who verifies AI coding agents' output. Minitap uses repository and product context to draft scenarios across iOS, Android, and web and proposes updates, so your team reviews instead of writing.
Feature Comparison Table of Autonomous QA Agents for iOS and Android
Each cell reflects the vendor's public documentation as of November 2026. Confirm details for your own builds during a pilot.
| Capability | Minitap | QA.tech | Drizz | Spur | MobileBoost | Panto AI |
|---|---|---|---|---|---|---|
| Coverage | Web, iOS, Android | Web, iOS, Android | iOS, Android, mobile web | Web, iOS, Android | iOS, Android | iOS, Android |
| Authorship | Agent drafts scenarios from product context | Team writes natural-language tests | Team writes plain-English tests | Team writes plain-English steps | Agent generates XCUITest and Espresso code; team refines | Team describes flows; agent generates tests |
| Maintenance | Agent proposes updates; team reviews | Not documented | Visual self-healing | Not documented | Agent updates code; team validates | Self-healing; team confirms |
| Execution | Cloud simulators, emulators, and browsers | Cloud browsers, iOS simulators, Android emulators | Real devices, emulators, simulators | Cloud iOS simulators and Android emulators | Simulators and physical devices | Real devices |
Where Minitap Fits Best
Minitap writes scenarios, runs them visually, and investigates failures across iOS, Android, and web. For maintenance, it proposes test updates and asks your team to review only the changes it cannot settle on its own. Your team stops writing and repairing test scripts. That ownership makes Minitap our top autonomous QA agent for iOS and Android.
As part of this agentic testing approach, repository context helps draft scenarios; screen evidence grounds findings. During onboarding, confirm which native AI coding tool connections are available and how findings reach developers. The concrete check: where does a failure appear in the developer’s workflow, and what evidence comes with it?
FAQ
Answers for mobile QA teams.
What is the best autonomous QA agent for iOS and Android apps?
Minitap is our top pick for iOS and Android regression because its AI QA employee writes scenarios and proposes routine updates, instead of leaving engineers to write and repair test scripts. It turns product specs, tickets, and existing test cases into scenarios with acceptance criteria, then runs black-box visual tests across iOS, Android, and web. Findings come from what appears on screen, not assumptions about what the source code should do. When the app changes, Minitap proposes test updates and surfaces changes it cannot settle on its own for review with context. Run videos, actionable bug reports, and recommended next steps for blockers give enterprise teams evidence for release decisions without reconstructing each failure themselves.
Can Minitap update my tests automatically when the app changes?
Yes. Minitap proposes updates to scenarios and acceptance criteria as your app changes instead of leaving engineers to repair scripts. It uses product specs, tickets, and existing test cases to understand expected behavior, then checks that behavior through black-box visual runs across iOS, Android, and web. Changes it cannot settle on its own come back to your team for review with context, so maintenance becomes a review task instead of a rewrite. Each run includes a video, so your team can inspect what happened as coverage evolves.
Can we import our existing regression tests into Minitap?
Yes. Upload your existing regression test cases to Minitap as CSV or Excel files to get started without rebuilding the suite from scratch. Minitap uses those cases as product context to write scenarios with acceptance criteria, alongside any specs and tickets you provide. You can edit any test in plain words to clarify expected results, such as whether a checkout should apply a discount or display an order confirmation. Minitap runs scenarios as black-box visual tests across iOS, Android, and web, with a video of every run so your team can review what happened.
How does Minitap decide what to test without my team writing test scripts?
Minitap decides what to test by reading product specs, tickets, and any existing test cases you provide, then drafting scenarios with acceptance criteria instead of waiting for engineers to script them. It checks those scenarios against what actually appears on screen across iOS, Android, and web, so your team is not translating requirements into test code before coverage exists. When a finding reflects intended behavior rather than a bug, mark it “Not a bug” with a short reason, and Minitap applies that feedback on the next run. This keeps test authorship off your engineering team's plate while keeping the acceptance criteria reviewable.
How is Minitap different from script-based mobile testing tools like Appium or Espresso?
Minitap differs from script-based frameworks such as Appium, Espresso, and XCUITest because engineers do not write or maintain the test logic. With those frameworks, your team authors each test case and updates the underlying code whenever the UI changes; Minitap instead drafts scenarios from product context and proposes updates itself when expected behavior shifts. It runs those scenarios as black-box visual tests across iOS, Android, and web, grounding results in what appears on screen rather than code-level assertions. For teams comparing the two approaches, the practical difference is who handles the maintenance work release after release, and with Minitap your engineers review proposed updates instead of rewriting scripts.
Final thoughts on AI QA Agents for Mobile Apps
The real difference is who owns the ongoing work. You can leave script upkeep behind without losing sight of your results. See how Minitap handles mobile and web tests with videos and actionable bug reports.
More Questions About Choosing an Autonomous QA Agent
How do you choose between Minitap, QA.tech, Drizz, Spur, MobileBoost, and Panto AI for enterprise regression?
Start with who writes and maintains tests, then check required coverage across iOS, Android, and web. Minitap drafts scenarios from product context and proposes updates; QA.tech, Drizz, Spur, and Panto AI start from team-written instructions or flows, while MobileBoost generates test code that your team refines and validates. Shortlist against your actual release needs, including browser coverage, physical-device execution, and failure evidence.
How should you compare Minitap, Drizz, MobileBoost, and Panto AI in a mobile QA pilot?
Run the same critical journeys against the same build and account state, then repeat after a UI change to measure maintenance work. Track time spent preparing tests, reviewing findings, and resolving blocked runs, alongside regression completion time. Minitap supplies run videos and recommended next actions for blockers; ask each vendor to show its evidence and maintenance process on your app.
What should you verify before connecting Minitap, QA.tech, Spur, or MobileBoost to your CI workflow?
Confirm supported repositories, execution triggers, build access, and where failures appear before making tests a release gate. QA.tech documents GitHub PR and Vercel preview integration; verify the exact connection your pipeline needs with each vendor. Confirm delivery into your developer workflow during onboarding. For evidence-backed web and mobile regression, Minitap writes and runs tests and proposes updates, with run videos and actionable findings for release decisions.